
Noindex is a powerful tool that helps website administrators control how Google indexes their content. When used correctly, this tag can help optimize SEO, prevent unnecessary pages from appearing in search results, and improve the overall quality of your website. However, if applied incorrectly, it can cause your site to lose significant traffic. So, what is Noindex, when should you use it, and how can you implement it effectively? Let's join Markdao to find out in the article below!
What is Noindex?
In SEO, not every page on a website needs to be indexed by Google. Some pages provide no value to users or may even harm your overall SEO strategy. This is where the Noindex tag comes into play.
Noindex is an attribute within a meta robots tag or HTTP header used to instruct search engines not to index a specific webpage. When a page is tagged this way, Googlebot and other search bots will not display it in search results, even though the page still exists on your website.
For example, you can add it to a page using a meta tag in the <head> section like this:
<meta name="robots" content="noindex">
Noindex helps administrators control how content appears on Google, keeps unnecessary pages from being indexed, and optimizes your overall SEO strategy.
How Google handles Noindex pages
When Googlebot crawls a page with this tag, it follows this process:
1. Access the page: Googlebot can still crawl and read the page content unless instructed otherwise via robots.txt.
2. Identifying Noindex: If this tag is detected in the HTML or HTTP header, Google will acknowledge the directive.
3. No indexing: The page will not appear in Google search results, even if it has many backlinks pointing to it.
4. Potential removal from the index: If the page was previously indexed, Google may remove it from search results after some time.
Note: Google may still continue to crawl the page Noindex if there is no additional nofollow directive or block in robots.txt. Therefore, if you want Google to stop crawling the page entirely, you need to combine several different methods.
Comparing with Nofollow – Two easily confused terms
Although both relate to how search engines process websites, Noindex and Nofollow serve different purposes:

When should you use them?
- Noindex: Use for pages with no SEO value, such as shopping cart pages, internal pages, or pages with duplicate content.
- Nofollow: Used to prevent Google from passing SEO value through links such as advertisements or user-generated content.
Understanding the difference between these two tags helps you implement a more effective SEO strategy and avoid unnecessary mistakes.
5 Reasons why a website might be noindexed
A website can be Noindexed for various reasons, not just due to intentional settings but also technical errors. If your site is not appearing on Google, check the following causes:
1. Inconsistent use of www and non-www domains
One common error is when a website is accessible in both versions:
- https://www.example.com
- https://example.com
Google treats these as two different versions of the same website. If you do not set up a canonical version and proper 301 redirects, it may lead to one of the versions being Noindexed.
2. Google cannot find your website
If Google cannot crawl your site, it will be unable to index your content, leading to unintended NoindexingPossible causes include:
- The new website does not yet have many backlinks.
- No signals have been sent to Google to request crawling.
- The website has connection errors or is being blocked by the hosting provider.
3. Errors in the robots.txt file
The robots.txt file is where administrators instruct Googlebot on which pages should or should not be crawled. If this file blocks the entire website or a critical section, Google will be unable to index those pages.
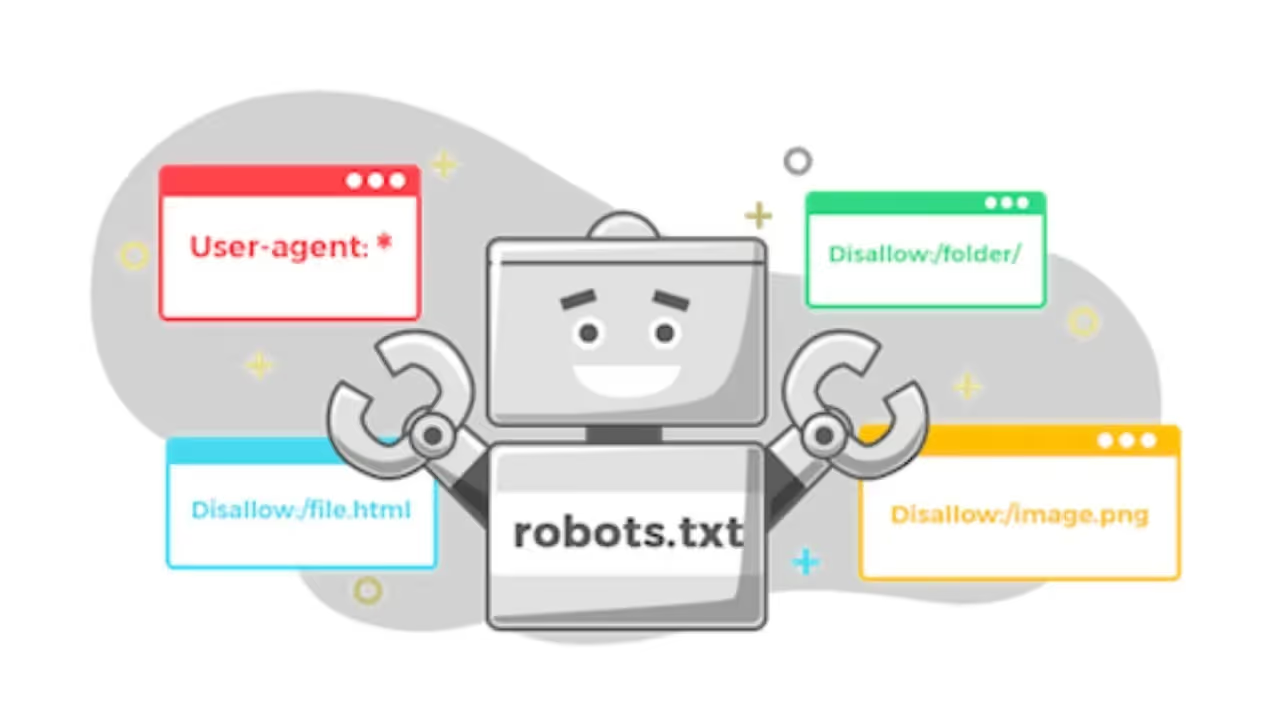
Example of an error in robots.txt:
User-agent: *
Disallow: /
This command prevents Google from crawling the entire website, causing all pages to be Noindexed.
4. Missing sitemap.xml
A sitemap.xml acts as a map that helps Google understand your website structure and crawl it more efficiently. If you do not have a sitemap or have not submitted one to Google, indexing may be delayed or miss many important pages.
5. Page load speed is too slow
Google prioritizes indexing pages with fast load speeds. If your website is too slow, Googlebot may abandon the crawl, leading to a status of not yet or not indexed.
Common causes of slow website performance include:
- Weak servers or poor-quality hosting.
- Unoptimized images and CSS/JS files.
- Lack of caching.
When should you use Noindex?
The Noindex tag is a powerful SEO tool that helps web administrators control which content is indexed by Google. However, improper use can cost your website valuable ranking opportunities. Here are the scenarios where you should proactively use Noindex to optimize your SEO strategy.
1. Pages with duplicate or low-quality content
Google always prioritizes high-quality, unique content. If your page contains content that duplicates other pages on your site or is considered thin content, you should use Noindex to avoid being penalized by Google.

Example:
- Pagination pages such as example.com/blog/page/2/
- Printable version of the page (print-friendly versions)
- Pages with thin content or no value to users
2. Thank You pages or transaction confirmation pages
Pages such as "Thank you for signing up", "Order confirmation", "Appointment confirmation" do not need to appear on Google because they do not provide valuable information to searchers.
If Google indexes these pages, users might access them directly from search results without going through the registration or transaction process, which reduces website performance.
3. Login, shopping cart, and personal account pages
Pages such as login, cart, and my account do not provide SEO value and do not need to appear in search results.
For example:
- example.com/login
- example.com/cart
- example.com/my-account
4. Tag, category, or archive pages (on CMS platforms like WordPress)
In many CMS systems such as WordPress, Shopify, tag, category, or archive pages can cause duplicate contentissues. If left unchecked, Google may index a large number of pages with similar content, which can lower your overall SEO quality.
For example:
- example.com/tag/seo-tips/
- example.com/category/marketing/
5. Pages under testing or development
If you are testing a new interface or building content that isn't finished yet, use a Noindex tag temporarily to prevent Google from indexing pages that aren't ready.
6. Pages containing sensitive or non-public information
Certain pages such as internal policies, company documents, or A/B test pages do not need to be indexed.
For example:
- example.com/private-policy-internal/
- example.com/test-landing-page/
You can use or completely block access using .htaccess or a password.
How to use the Noindex tag effectively for SEO
The Noindex tag is an extremely important tool in SEO that helps webmasters control which pages are indexed by Google. Used correctly, it helps you remove low-value pages and focus your SEO efforts on important content. Conversely, if applied incorrectly, you could accidentally remove important pages from Google, causing your website to lose significant traffic.
So how do you use intelligently and effectively?
1. Add the Meta Robots Noindex tag to the page you want to block
The simplest and most common way to request that Google not index a page is to use the Meta Robots Noindextag. You just need to add this code to the <head> section of the page you want to block:
<meta name="robots" content="noindex, follow">
- Noindex: Prevents Google from indexing the page.
- FollowAllows Google to continue following links on the page, helping to distribute SEO value to other pages.

Note:
If you want Google to not follow links on the page, replace "follow" with "nofollow":
<meta name="robots" content="noindex, nofollow">
- If you accidentally Noindex an important page (e.g., homepage, strategic articles), Google will stop displaying that page in search results, significantly reducing traffic.
2. Use Noindex via X-Robots-Tag (for PDFs, images, and documents)
If you want to block PDFs, images, or documents on your server, you cannot use Meta Robots; you must use the X-Robots-Tag in the HTTP header.
Example: If you want to block a PDF file, add the following to the .htaccess file on your Apache server:
<Files "example.pdf">
Header set X-Robots-Tag "noindex, nofollow"
</Files>
Or if you are using Nginx, add this to your server configuration:
location ~* \.pdf$ {
add_header X-Robots-Tag "noindex, nofollow";
}
When should you use the X-Robots-Tag?
- When you want to block document files (PDF, DOCX, CSV, etc.) from appearing on Google.
- When you want to block unwanted images from Google Image Search.
3. Blocking pages in robots.txt – But don't use it as a substitute for Noindex!
Some people mistakenly believe that simply blocking a page in robots.txt will prevent Google from indexing it. This is incorrect! If Google has already indexed the page, it may still appear in search results; it just means Google can no longer crawl the page.
Common mistake example:
User-agent: *
Disallow: /private-page/
Mistake: Even though Google cannot crawl the content of /private-page/, if this page has backlinks from other websites, it can still appear in search results.
Correct solution: If you want to completely block a page from Google, use the Meta Robots Noindex tag instead of just using robots.txt.
4. Combine with canonical tags to handle duplicate content
If your website has multiple versions of the same content (e.g., pages with dynamic URLs or pagination), you have two ways to handle it:
1. Use Noindex to block unnecessary pages.
2. Use Canonical to specify the primary version.

Example of duplicate content caused by pagination:
- example.com/blog/page/1/
- example.com/blog/page/2/
- example.com/blog/page/3/
To prevent Google from indexing each individual subpage, you can add Noindex to the subpages (page/2/, page/3/...), while still allowing Google to follow the links:
<meta name="robots" content="noindex, follow">
Alternatively, if you want to keep the main page (page/1/), use the Canonical tag to designate it as the unique version:
<link rel="canonical" href="https://example.com/blog/page/1/">
When should you use Noindex?
- When you want to completely remove a page from search results.
When should you use Canonical?
- When you want to consolidate the SEO value of multiple pages into one primary page without deleting them.
5. Check Noindex pages using Google Search Console
After adding it, you need to verify that Google has recognized and processed it correctly. How to check:
Use the "URL Inspection" tool in Google Search Console:
- Enter the URL into the inspection box.
- If you see the line "Excluded by 'noindex' tag", it means Google has received the command successfully.
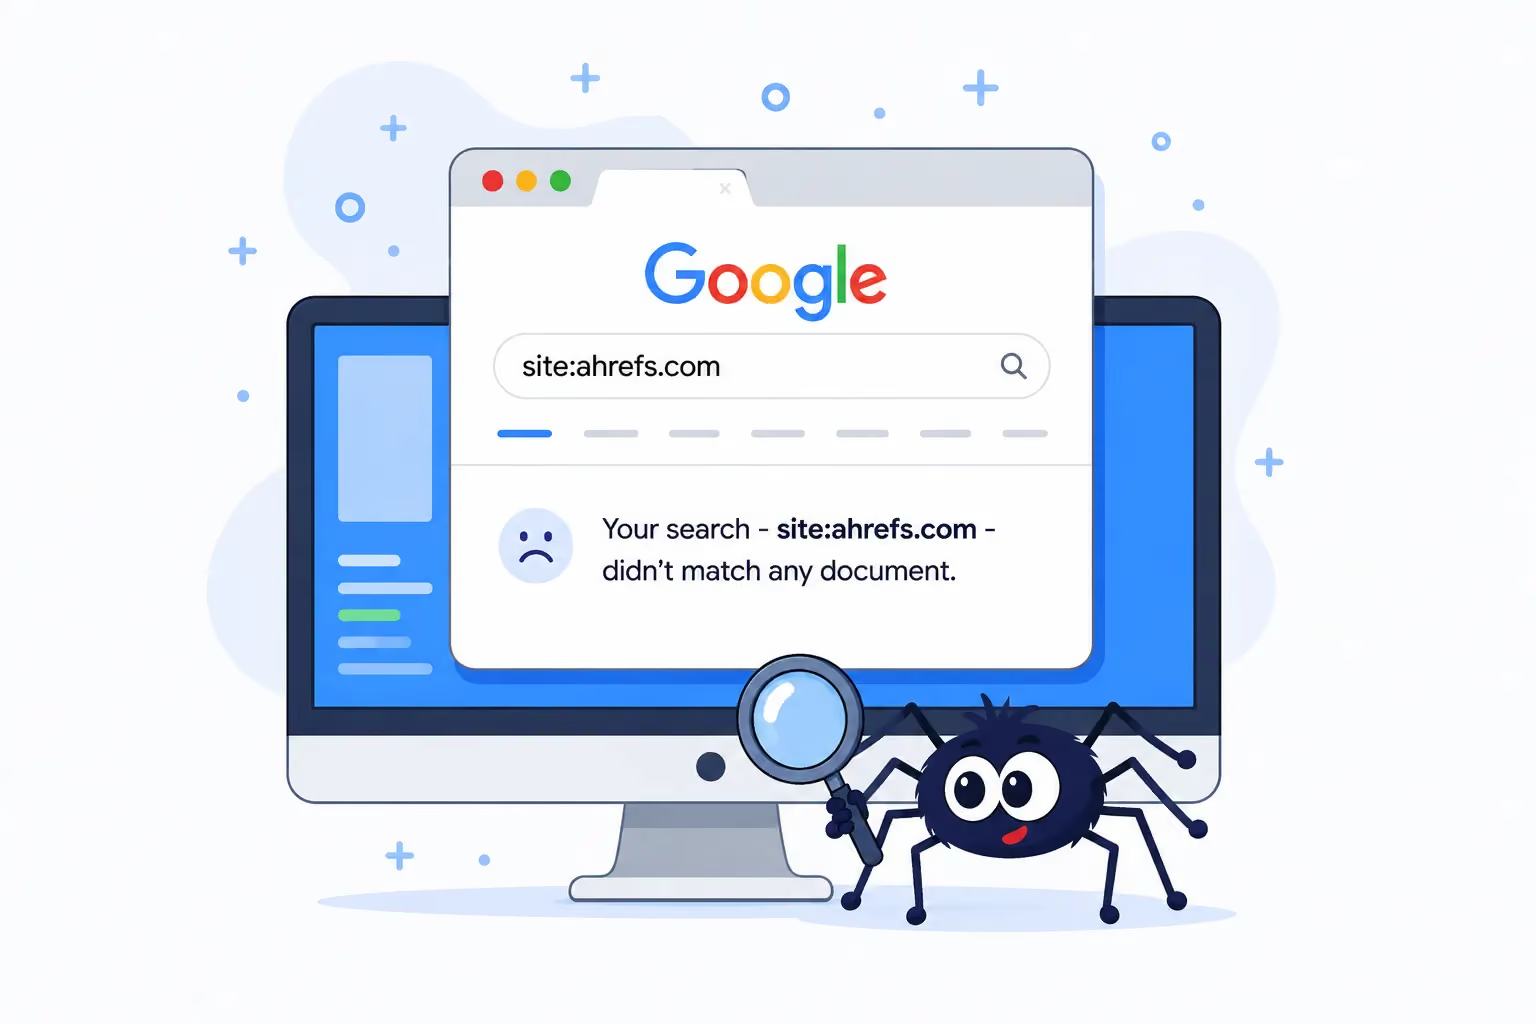
Check directly on Google using the site: command
Type into Google: site:example.com/private-page/
- If the page does not appear, it means Noindex is working properly. If the page is still there, Google may not have updated yet.
The Noindex tag is a powerful SEO tool, but it must be used correctly to avoid harming your website's traffic. Remember:
Use Noindex when:
- You need to remove low-value pages from Google.
- You want to block thank-you pages, login pages, or shopping carts.
- You are handling duplicate content or pagination.
Do not use Noindex when:
- You want to retain the page's ranking and SEO value.
- You mistakenly believe Noindex will help speed up website indexing.
How to fix a website that has been noindexed
If your website has been Noindex ed unintentionally, you need to identify the cause and fix it quickly to avoid losing traffic from Google. Below are the important steps to help you resolve this situation.
1. Check and remove the tag
Meta tag Noindex may have been accidentally added to the website, preventing Google from indexing the page.
How to check:
- Press Ctrl + U to view the page source or use Inspect Element.
- Search for the <meta name="robots" content="noindex, follow"> tag.
How to fix:
- If Noindexis present, remove it or change it to <meta name="robots" content="index, follow">.
2. Check the robots.txt file
The robots.txt file may be blocking Google from crawling your website.
How to check:
Visit yourwebsite.com/robots.txt and look for the following lines:
User-agent: *
Disallow: /
- If you see these lines, Google is being blocked from accessing your entire website.
How to fix:
Remove them or change them to:
User-agent: *
Allow: /
3. Check Google Search Console
Google Search Console helps identify which pages are being Noindexed.
How to check:
- Go to Google Search Console → "URL Inspection" and enter the page you want to check.
- If it shows "Page excluded by Noindex", you need to adjust the page.
How to fix:
- After making changes, select "Request Indexing" so Google can update it.
4. Update sitemap.xml and resubmit to Google
If your website doesn't have a sitemap or it hasn't been updated, Google might skip indexing your site.
How to fix:
- Create or update your sitemap.xml file.
- Resubmit the sitemap in Google Search Console under the "Sitemaps" section.
5. Check page loading speed
Websites with slow loading speeds may be ignored by Google during crawling.
How to fix:
- Use Google PageSpeed Insights to check performance.
- Improve speed by optimizing images, using a CDN, and minifying unnecessary code.
Website Noindex can severely impact SEO. To fix this, check for and remove it from Meta tags, robots.txt, and Google Search Console, update your sitemap, and improve page load speed. Once fixed, request re-indexing from Google to ensure your website functions properly on search engines.
Conclusion
The Noindex tag is an important SEO tool that helps control which content is indexed on Google. However, if used incorrectly, it can cause your website to lose significant traffic. By understanding the causes, applying it appropriately, and fixing unintended errors, you can effectively optimize your SEO performance. Check your website regularly to ensure your pages appear on Google and reach your target audience.